The Pentagon has narrowed the role of several controversial artificial intelligence technologies in its polygraph research. But an important question remains unanswered: how does that decision fit with federal budget plans that still describe AI-assisted credibility assessment?
On September 30, 2026, the Defense Counterintelligence and Security Agency (DCSA) clarified that its active “Modernizing Polygraph” research does not incorporate generative AI, large language models, facial-action coding, micro-expression analysis or vocal analysis. The clarification became public through Defense News reporting published October 5.
The statement appears to exclude technologies once discussed as part of a broader effort to analyze speech, behavior and emotional responses during security interviews. However, earlier government budget documents continue to identify machine-learning scoring, automated decision aids and non-contact physiological monitoring as elements of a program called Polygraph Next.
The distinction matters. Removing certain AI applications from active research does not necessarily mean abandoning automated polygraph analysis. It also does not establish that the technologies remaining in budget proposals have been validated or deployed.
Understanding what actually changed requires separating past research concepts, current development activities and future funding plans.
DCSA Drew a Clear Boundary Around Several AI Technologies
DCSA’s latest statement was unusually specific about what its active Modernizing Polygraph effort does not include.
Generative AI and large language models were excluded, as were technologies intended to interpret facial actions, micro-expressions and vocal characteristics.
According to Defense News, the agency indicated that these technologies are outside the current research effort while leaving open the possibility of evaluating emerging scientific capabilities in the future.
That distinction is significant because earlier Defense Department research appeared to consider a broader range of behavioral and linguistic information.
Declassified presentations obtained by Defense News described experimental work dating back to 2019 involving sentiment analysis and deceptive-speech detection. One concept presented in May 2025 depicted an automated interview system using cameras, microphones and language models to help interpret an interviewee’s emotional state.
Those historical concepts illustrate how ambitious the modernization effort had become.
They do not, however, establish that such systems were successfully validated, adopted for operational screening or approved for routine personnel decisions.
DCSA’s clarification now places several of those experimental approaches outside the active research project it identified.
What remains unclear is whether the agency has formally ended those research lines, transferred them elsewhere or simply distinguished them from a narrower development effort.
Pentagon Polygraph Modernization Still Includes AI Scoring in Budget Plans
The strongest reason not to interpret DCSA’s clarification as a wholesale cancellation of AI lies in its own budget documentation.
The DCSA FY2027 research-and-development budget justification, dated April 2026, identifies Polygraph+/Polygraph Next as a program intended to improve federal credibility-assessment technology.
The document describes several areas of development:
- Automated scoring and decision-support capabilities.
- Non-contact physiological sensing.
- Centralized storage and analytical systems.
- Machine-learning algorithms used to assess recorded information.
- Independent validation, prototype evaluation and operational field testing.
The proposal requests $6.421 million for FY2027 and projects further funding through FY2031. Its five-year figures total approximately $30.34 million.
These are budget request and planning figures, not proof that the entire amount has been appropriated, spent or committed to particular technologies.
The budget also describes plans for operational pilots involving different polygraph applications and test formats. Those plans demonstrate an intended development pathway, not evidence that the proposed tools are already standard equipment in federal examinations.
Still, the inclusion of AI/ML-based scoring algorithms presents an obvious question.
If DCSA’s active research excludes generative AI and particular forms of behavioral analysis, what kinds of machine learning remain part of Polygraph Next?
The answer may involve an important technical distinction.
A language model attempting to infer dishonesty from someone’s words is not the same as an algorithm evaluating physiological measurements collected during a conventional examination.
Both may be described broadly as AI, but they work with different information and make different types of inferences.
Polygraphianz previously examined those differences in Polygraph Next: Can AI Make Lie Detection More Accurate?, including the opportunities and scientific limitations associated with automated scoring and contactless sensors.
The latest clarification makes that distinction more consequential because DCSA has explicitly excluded some technologies while leaving the status of other analytical approaches less clear.
The Program Names Reveal a Larger Transparency Problem
There is another complication: the terminology used across government materials is not consistent.
Earlier research documents referred to Credibility Assessment Modernization.
The FY2027 budget uses Polygraph+/Polygraph Next.
The September 30 clarification, meanwhile, addresses an active effort called Modernizing Polygraph.
Those labels might represent different projects, overlapping research portfolios or successive stages of one modernization initiative. The available documents do not establish their precise relationship.
That uncertainty creates a problem for interpreting the government’s position.
A statement excluding technologies from one named project cannot automatically be applied to every related research program.
Conversely, a budget document describing AI development does not establish that every previously proposed system remains active.
The difference between three stages of technological development is especially important.
Research concepts establish what investigators have considered possible or worth studying.
Budget proposals indicate what an agency intends to develop or fund.
Operational deployment requires separate evidence that a system has moved into actual use.
Confusing these stages can make abandoned concepts appear operational or make an active research program appear cancelled.
For government employees and security-clearance applicants, that is more than an accounting issue. It affects whether they can understand what technology may influence a credibility assessment and how that technology has been evaluated.
A definitive explanation would require DCSA to identify how its project names relate, which technical components remain active and what has changed since earlier plans were published.
Automated Polygraph Scoring Cannot Solve Every Scientific Problem
The narrower research scope also highlights an underlying limitation of lie-detection technology.
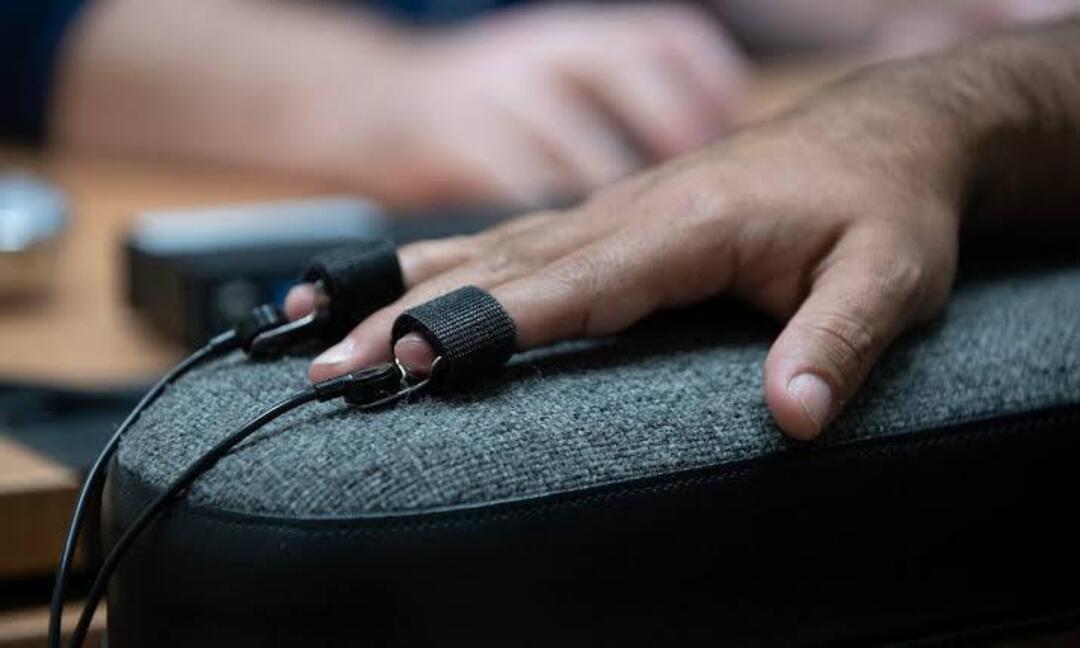
A conventional polygraph records physiological activity, including changes in breathing, cardiovascular responses and skin conductance.
The instrument does not directly measure deception.
Instead, an examiner interprets physiological responses recorded during a structured questioning process.
Automated scoring may make parts of that interpretation more consistent. A properly designed algorithm can apply defined analytical procedures repeatedly and potentially reduce some forms of variation between examiners.
But consistency and validity are separate questions.
An algorithm might reliably identify a physiological response without establishing why that response occurred.
Anxiety, fear, surprise, uncertainty and concern about an accusation can all affect physiological activity. A numerical score does not automatically distinguish those influences from deception.
That problem was identified well before modern machine learning became part of the discussion. The National Research Council’s 2003 review, The Polygraph and Lie Detection, found that the physiological measures used by polygraphs are not uniquely associated with deception.
AI does not eliminate that scientific limitation simply by processing more observations or detecting smaller changes.
This creates two different standards for evaluating modernization.
A new system could improve the technical quality of physiological measurement while providing little improvement in the accuracy of credibility judgments.
Alternatively, independently validated analytical methods might demonstrate meaningful improvements under particular testing conditions.
The evidence must establish which outcome has actually occurred.
DCSA’s proposed validation studies and operational pilots are therefore among the most consequential aspects of Polygraph Next. Their results would matter more than whether a system is marketed as artificial intelligence.
The Clarification Does Not Establish a Change in Current Examinations
For people undergoing federal polygraph testing, the immediate implications should not be overstated.
The September clarification concerned active research and development. It was not presented as a comprehensive announcement changing existing examination procedures.
The available reporting does not establish that current federal examinees are routinely assessed by generative language models, facial-emotion recognition systems or the other technologies excluded from the named research effort.
Nor does it demonstrate that machine-learning scoring has become the operational standard for all federal polygraph examinations.
Those distinctions matter because national-security credibility assessments can influence access to sensitive duties and information.
When a technology may contribute to a high-stakes personnel decision, examinees and oversight authorities have legitimate interests in understanding its purpose, reliability and limitations.
Automated decision support also introduces a potential risk known as automation bias: the tendency to place excessive confidence in a computer-generated recommendation.
Even where a human examiner retains final responsibility, a persuasive-looking score could influence professional judgment.
A meaningful human-review process therefore requires more than the presence of a person who receives the algorithm’s output. It requires an ability to recognize uncertainty, question the analysis and evaluate evidence independently.
Private employers should be especially cautious about interpreting the Pentagon’s research as a model they can automatically adopt.
Federal security vetting operates under different rules from ordinary employment screening. In the United States, the Employee Polygraph Protection Act generally restricts private-employer lie-detector testing, subject to specific exceptions. Other jurisdictions have their own employment, consent and privacy requirements.
A federal research initiative does not independently establish that a comparable workplace system is lawful, reliable or appropriate elsewhere.
What Evidence Would Resolve the Pentagon’s AI Polygraph Uncertainty?
Several developments would provide a clearer answer than another broad statement about the future of AI.
The first would be an official explanation of the relationship between Modernizing Polygraph, Polygraph Next and the earlier Credibility Assessment Modernization work.
Such an explanation could establish whether DCSA narrowed one existing project, reorganized multiple research efforts or discontinued specific experimental technologies.
The second would be updated technical documentation identifying which forms of automated analysis remain under development.
That information would help distinguish physiological scoring algorithms from language-based deception analysis and behavioral emotion-recognition systems.
Third, independent validation results would make it possible to examine performance rather than intentions.
For any proposed system, the relevant evidence should include the testing population, methods used to establish ground truth, rates of incorrect classifications and performance under realistic examination conditions.
Accuracy measured in a controlled experiment involving volunteers may not transfer directly to high-pressure national-security investigations.
Finally, clearer documentation of human oversight would establish how machine-generated outputs are intended to influence examinations.
A system that assists an examiner in reviewing physiological data raises different governance questions from a system that independently assigns credibility classifications.
Those questions become particularly important when results may affect careers, assignments or access to classified information.
The Next Test Is Transparency, Not Another AI Promise
DCSA’s clarification provides a meaningful update to Pentagon polygraph modernization. Several high-profile AI approaches, including generative language models and facial- and voice-based analysis, are outside the active research effort described by the agency.
Yet the broader modernization picture remains unsettled.
The FY2027 budget continues to describe automated scoring, machine-learning algorithms, non-contact sensing and planned operational testing. The public record does not fully explain how those proposals relate to the narrower research scope announced in September.
It would be inaccurate to declare that the Pentagon has abandoned artificial intelligence in polygraph modernization. It would also be premature to assume that all previously discussed AI technologies remain under development.
The central issue is now one of accountability: which technologies are actually being pursued, what scientific evidence supports them, and what safeguards will govern their use?
Until those questions receive clearer answers, the most responsible interpretation is that the Pentagon has narrowed part of its AI research agenda without fully resolving the future role of automated credibility assessment.